
Why Your RAG Pipeline Misses the Perfect Answer Just Because of a Synonym
Retrieval-augmented generation promises to find information based on meaning rather than exact keywords, but subtle shifts in vocabulary can still push critical documents out of reach.

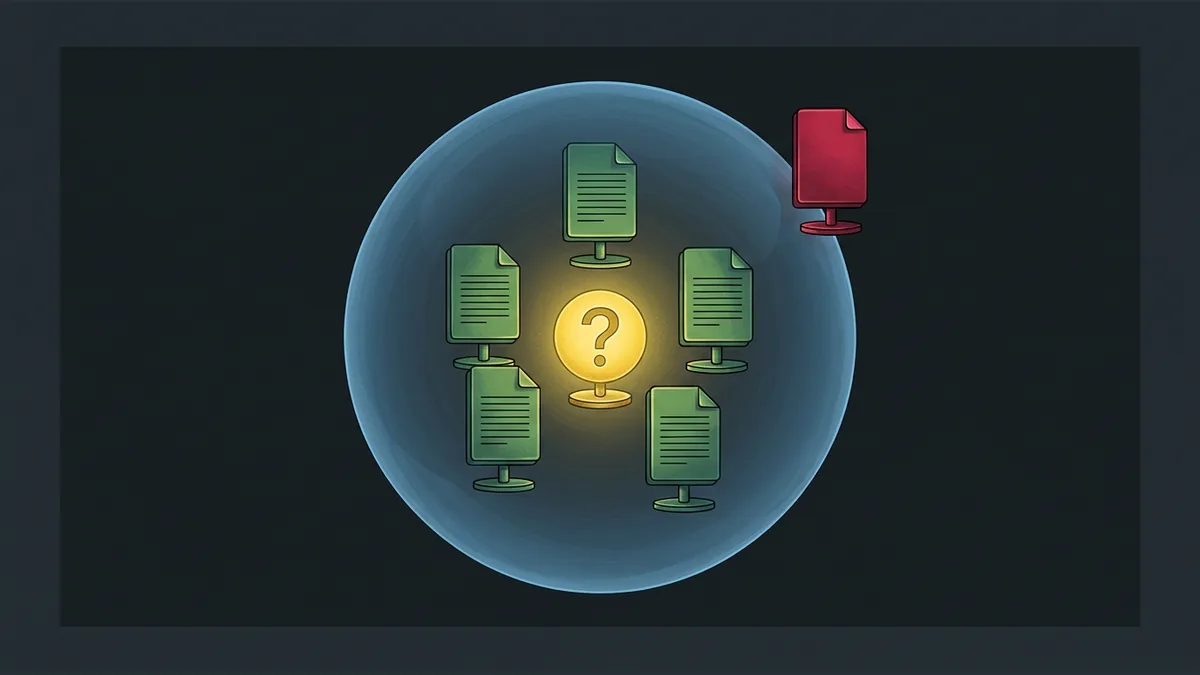

Retrieval-Augmented Generation (RAG) has become the standard architecture for grounding large language models in private or domain-specific data. By converting documents and user queries into numerical representations, RAG systems attempt to match the user's intent with the most relevant source text. However, despite the promise of "semantic" search, these pipelines can still fail due to simple vocabulary mismatches.
At the core of this issue is how embedding models represent text. These models translate words, sentences, or entire documents into vectors of floating-point numbers within a high-dimensional space, where the mathematical distance between two vector points serves as the measure of their relative similarity [f1]. In typical word and text embeddings, this vector space is highly complex, often utilizing dimensions such as 256, 512, or 1024 [f2].
Why Synonyms Create Vector Drift
While dense vectors are designed to capture meaning rather than exact spelling, they are not infallible. The relative positions of words in any embedding space are highly dependent on the specific corpus of text used to train the model, as well as the context in which those words appeared [f3]. Furthermore, because embedding vectors are task-specific, their spatial relationships can vary significantly depending on the model's training objective [f4]. If a model was trained on general web text, it may not associate technical jargon with everyday synonyms in the way a human expert would.
Consider a hypothetical scenario where an organization maintains a technical database containing a crucial troubleshooting document. This document uses the formal engineering term "transient voltage spike" to describe a specific power issue. A field technician, searching for a quick solution, enters the query "temporary power surge." To a human reader, these two phrases are semantically identical in this context. However, the embedding model maps the query "temporary power surge" closer to consumer-grade surge protector product descriptions because of how those terms co-occurred in its training data. Because the actual troubleshooting document uses formal jargon, its vector representation sits just beyond the top-5 retrieval threshold for the technician's query. As a result, the RAG pipeline fails to retrieve the critical document, leaving the LLM with no context to answer the question.
Bridging the Semantic Gap
To mitigate these retrieval failures, developers must look beyond basic dense vector search. Some of the world's most robust search systems implement multi-layered strategies to handle vocabulary variation. For example, to address synonym variations in search queries, systems like Google Search have utilized offline LLM inference to pre-compute and cache extensive lists of synonyms across dozens of languages [f5].
For enterprise RAG pipelines, relying solely on a single embedding model to bridge the gap between casual queries and highly specialized documentation is a risky strategy. Implementing hybrid search, which combines dense vector retrieval with traditional keyword-based BM25 search, or utilizing query expansion techniques to inject synonyms before vector generation can prevent critical information from falling just outside the retrieval boundary.
Your reaction
Loading reactions…


Comments 0
Review comments